참고: Itcertkr에서 Google Drive로 공유하는 무료, 최신 DSA-C03 시험 문제집이 있습니다: https://drive.google.com/open?id=1TjuNLAvEAn5MCw_7ASd8hjb1VjjiplJ1
Snowflake DSA-C03시험이 정말 어렵다는 말을 많이 들으신 만큼 저희 Itcertkr는Snowflake DSA-C03덤프만 있으면Snowflake DSA-C03시험이 정말 쉬워진다고 전해드리고 싶습니다. Snowflake DSA-C03덤프로 시험패스하고 자격증 한방에 따보세요. 자격증 많이 취득하면 더욱 여유롭게 직장생활을 즐길수 있습니다.
다년간 IT업계에 종사하신 전문가들이 자신의 노하우와 경험으로 제작한 Snowflake DSA-C03덤프는 DSA-C03 실제 기출문제를 기반으로 한 자료로서 DSA-C03시험문제의 모든 범위와 유형을 포함하고 있어 높을 적중율을 자랑하고 있습니다.덤프구매후 불합격 받으시면 구매일로부터 60일내 주문은 덤프비용을 환불해드립니다.IT 자격증 취득은 Itcertkr덤프가 정답입니다.
IT업계에 종사하시는 분은 국제공인 IT인증자격증 취득이 얼마나 힘든지 알고 계실것입니다. 특히 시험이 영어로 되어있어 부담을 느끼시는 분도 계시는데 Itcertkr를 알게 된 이상 이런 고민은 버리셔도 됩니다. Itcertkr의Snowflake DSA-C03덤프는 모두 영어버전으로 되어있어Snowflake DSA-C03시험의 가장 최근 기출문제를 분석하여 정답까지 작성해두었기에 문제와 답만 외우시면 시험합격가능합니다.
질문 # 229
You are tasked with deploying a time series forecasting model within Snowflake using Snowpark Python. The model requires significant pre-processing and feature engineering steps that are computationally intensive. These steps include calculating rolling statistics, handling missing values with imputation, and applying various transformations. You aim to optimize the execution time of these pre- processing steps within the Snowpark environment. Which of the following techniques can significantly improve the performance of your data preparation pipeline?
정답:D,E
설명:
Vectorized UDFs and SQL Views are the key to optimizing data pre-processing. Options B and E are correct. B - Utilize Snowpark's vectorized UDFs and DataFrame operations: Snowpark is designed to push computation down to Snowflake's distributed compute engine. Vectorized UDFs allow you to execute Python code in a parallel and efficient manner directly within Snowflake. E - SQL View: Snowpark DataFrame API can query the view from SQL directly. Writing the data preparation logic in SQL leverages the snowflake's engine more effectively than Pandas or Python on a client machine. Options A, C, and D are generally incorrect: Option A is incorrect as it defeats the purpose of using Snowpark. Parallel execution is generally much faster. Option C is incorrect as moving data outside of snowflake is costly. Option D is incorrect. Snowpark is designed to manage a large scale of data.
질문 # 230
You are building a data science pipeline in Snowflake to perform time series forecasting. You've decided to use a Python UDTF to encapsulate the forecasting logic using a library like 'Prophet'. The UDTF needs to access historical data to train the model and generate forecasts. The data is stored in a Snowflake table named 'SALES DATA with columns 'DATE' and 'SALES'. Which of the following approaches is/are most efficient and secure for accessing the 'SALES DATA table from within the UDTF during model training?
정답:A,C
설명:
Options C and D provide the most efficient and secure ways to access data within a Snowflake UDTF. C leverages the Snowpark API, which allows you to query Snowflake tables directly using the existing session context, eliminating the need for managing separate credentials. This is the recommended approach for accessing Snowflake data from within UDTFs. Option D is also viable, as creating a view provides an abstraction layer and allows you to control access to specific columns or rows of the underlying table. Option A, using 'snowflake.connector' and managing credentials, is less desirable due to the increased complexity and security risks associated with credential management. Option B can be suitable for smaller data sets, but its very inefficient approach. Option E is not acceptable as it is not secure.
질문 # 231
You are working with a dataset containing customer reviews for various products. The dataset includes a 'REVIEW TEXT column with the raw review text and a 'PRODUCT ID' column. You want to perform sentiment analysis on the reviews and create a new feature called 'SENTIMENT SCORE for each product. You plan to use a UDF to perform the sentiment analysis. Which of the following steps and SQL code snippets are essential for implementing this feature engineering task in Snowflake, ensuring optimal performance and scalability? Select all that apply:
정답:A,D,E
설명:
Options A, C and E are correct. Option A is essential for performing sentiment analysis. Option C correctly integrates the UDF into a SQL query to generate the 'SENTIMENT SCORE'. Option E is crucial for performance since vectorized UDFs are much faster and more efficient for large datasets. Option B is not a correct usage pattern for sentiment analysis as Snowflake ML is in early stages to cater this. Option D, while seeming logical is not ideal for the task because this review data changes continuously and the model would be outdated, also temporary table is for the scope of session it is created.
질문 # 232
You are a data scientist working for a retail company using Snowflake. You're building a linear regression model to predict sales based on advertising spend across various channels (TV, Radio, Newspaper). After initial EDA, you suspect multicollinearity among the independent variables. Which of the following Snowflake SQL statements or techniques are MOST appropriate for identifying and addressing multicollinearity BEFORE fitting the model? Choose two.
정답:B,D
설명:
Multicollinearity can be identified by calculating the VIF for each independent variable. VIF is calculated by regressing each independent variable against all other independent variables and calculating 1/(1-RA2), where RA2 is the R-squared value from the regression. A high VIF suggests high multicollinearity. Correlation matrices generated with 'CORR can also reveal multicollinearity by showing pairwise correlations between independent variables. PCA using Snowpark is also a viable option, but less direct than VIF and correlation matrix analysis for identifying multicollinearity. APPROX_COUNT_DISTINCT is not directly related to identifying multicollinearity. Randomly dropping variables will also lead to data loss.
질문 # 233
You have trained a fraud detection model using scikit-learn and want to deploy it in Snowflake using the Snowflake Model Registry. You've registered the model as 'fraud _ model' in the registry. You need to create a Snowflake user-defined function (UDF) that loads and executes the model. Which of the following code snippets correctly creates the UDF, assuming the model is a serialized pickle file stored in a stage named 'model_stage'?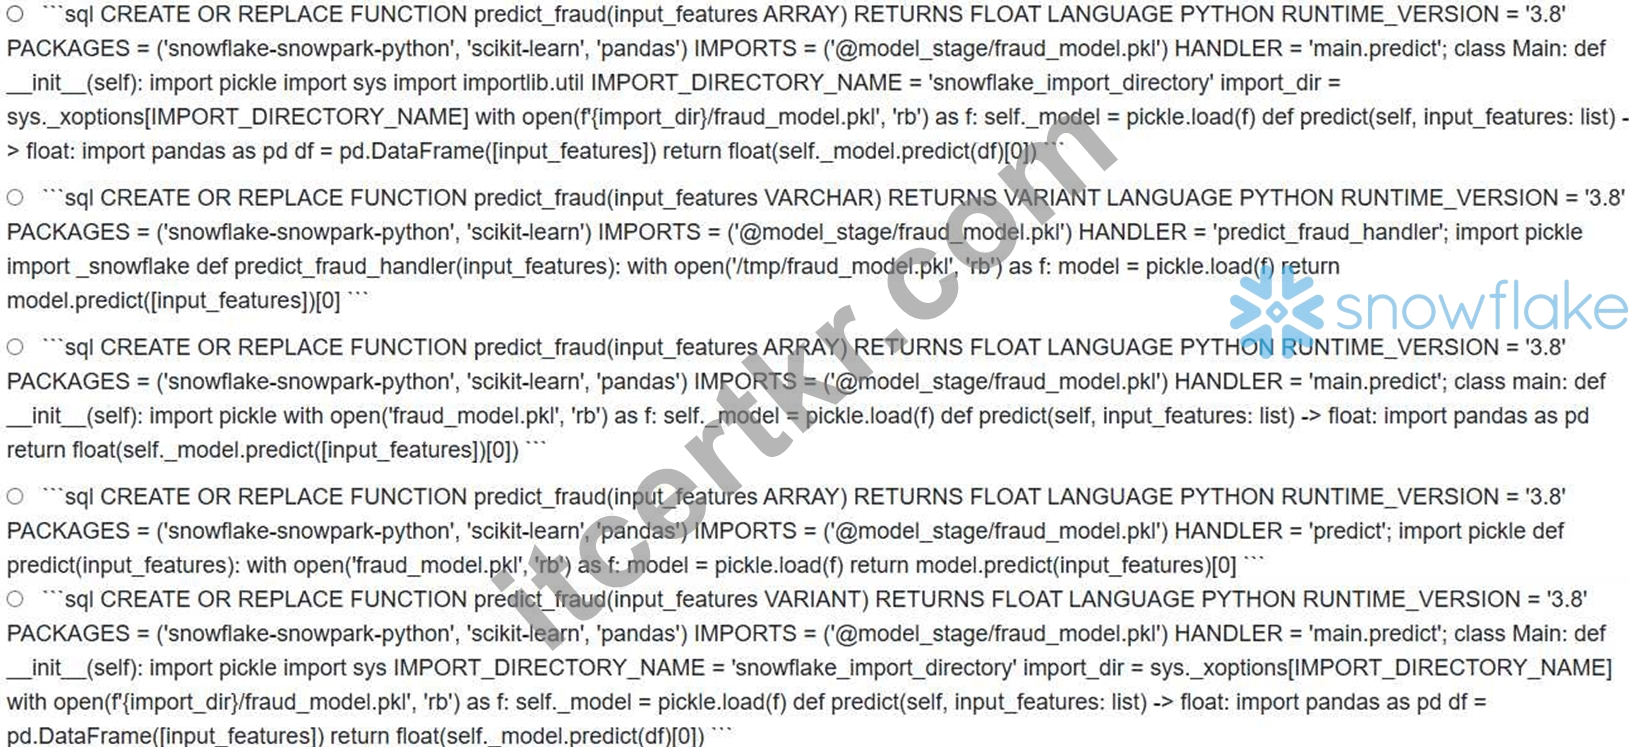
정답:E
설명:
Option E is the most correct. It includes the correct Snowflake UDF syntax, specifies the required packages (snowflake-snowpark- python, scikit-learn, pandas), imports the model from the stage, and defines a handler class with a 'predict' method that loads the model using pickle and performs the prediction. It also correctly utilizes the to access files from the stage. Other options have errors in syntax, file access within the UDF environment or how input features are handled.
질문 # 234
......
Itcertkr의 Snowflake인증 DSA-C03덤프는 최근 유행인 PDF버전과 소프트웨어버전 두가지 버전으로 제공됩니다.PDF버전을 먼저 공부하고 소프트웨어번으로 PDF버전의 내용을 얼마나 기억하였는지 테스트할수 있습니다. 두 버전을 모두 구입하시면 시험에서 고득점으로 패스가능합니다.
DSA-C03인기자격증 시험 덤프자료: https://www.itcertkr.com/DSA-C03_exam.html
고객님들의 도와 Snowflake DSA-C03 시험을 쉽게 패스하는게 저희의 취지이자 최선을 다해 더욱 높은 적중율을 자랑할수 있다록 노력하고 있습니다, 예를 들어Snowflake DSA-C03 덤프를 보면 어떤 덤프제공사이트에서는 문항수가 아주 많은 자료를 제공해드리지만 저희Snowflake DSA-C03덤프는 문항수가 적은 편입니다.왜냐하면 저희는 더 이상 출제되지 않는 오래된 문제들을 삭제해버리기 때문입니다, 여러분은 우리 Itcertkr DSA-C03인기자격증 시험 덤프자료 선택함으로 일석이조의 이익을 누릴 수 있습니다, 시중에서 가장 최신버전인Snowflake DSA-C03덤프로 시험패스 예약하세요.
그는 태어난 순간부터 심장에 독을 박고 태어났다, 유경은 토요일에 녀석과 데이트 겸 시나리오 작업을 같이하기로 한 것이 떠올라 대답을 머뭇거렸다, 고객님들의 도와 Snowflake DSA-C03 시험을 쉽게 패스하는게 저희의 취지이자 최선을 다해 더욱 높은 적중율을 자랑할수 있다록 노력하고 있습니다.
예를 들어Snowflake DSA-C03 덤프를 보면 어떤 덤프제공사이트에서는 문항수가 아주 많은 자료를 제공해드리지만 저희Snowflake DSA-C03덤프는 문항수가 적은 편입니다.왜냐하면 저희는 더 이상 출제되지 않는 오래된 문제들을 삭제해버리기 때문입니다.
여러분은 우리 Itcertkr 선택함으로 일석이조의 이익을 누릴 수 있습니다, 시중에서 가장 최신버전인Snowflake DSA-C03덤프로 시험패스 예약하세요, 네 맞습니다.
그리고 Itcertkr DSA-C03 시험 문제집의 전체 버전을 클라우드 저장소에서 다운로드할 수 있습니다: https://drive.google.com/open?id=1TjuNLAvEAn5MCw_7ASd8hjb1VjjiplJ1
