DOWNLOAD the newest ExamBoosts Databricks-Machine-Learning-Associate PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1eKlmJ9bqt2fWfM5YBXYNEqtvvb0hr3d-
Only if you download our software and practice no more than 30 hours will you attend your test confidently. Because our Databricks-Machine-Learning-Associate exam torrent can simulate limited-timed examination and online error correcting, it just takes less time and energy for you to prepare the Databricks-Machine-Learning-Associate exam than other study materials. It is very economical that you just spend 20 or 30 hours then you have the Databricks-Machine-Learning-Associate certificate in your hand, which is typically beneficial for your career in the future. Therefore, purchasing the Databricks-Machine-Learning-Associate guide torrent is the best and wisest choice for you to prepare your test.
You can easily get Databricks Databricks-Machine-Learning-Associate certified if you prepare with our Databricks Databricks-Machine-Learning-Associate questions. Our product contains everything you need to ace the Databricks-Machine-Learning-Associate certification exam and become a certified professional. So what are you waiting for? Purchase this updated Databricks Databricks-Machine-Learning-Associate Exam Practice material today and start your journey to a shining career.
>> Databricks Databricks-Machine-Learning-Associate Dumps Collection <<
As we entered into such a web world, cable network or wireless network has been widely spread. And it is easier to find an online environment to do your practices. This version of Databricks-Machine-Learning-Associate test prep can be used on any device installed with web browsers. We specially provide a timed programming test in this online Databricks-Machine-Learning-Associate Test Engine, and help you build up confidence in a timed exam. With limited time, you need to finish your task in Databricks-Machine-Learning-Associate quiz guide, considering your precious time, we also suggest this version of Databricks-Machine-Learning-Associate study guide that can help you find out your problems to pass the exam.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
NEW QUESTION # 74
A data scientist has been given an incomplete notebook from the data engineering team. The notebook uses a Spark DataFrame spark_df on which the data scientist needs to perform further feature engineering. Unfortunately, the data scientist has not yet learned the PySpark DataFrame API.
Which of the following blocks of code can the data scientist run to be able to use the pandas API on Spark?
Answer: C
Explanation:
To use the pandas API on Spark, which is designed to bridge the gap between the simplicity of pandas and the scalability of Spark, the correct approach involves importing the pyspark.pandas (recently renamed to pandas_api_on_spark) module and converting a Spark DataFrame to a pandas-on-Spark DataFrame using this API. The provided syntax correctly initializes a pandas-on-Spark DataFrame, allowing the data scientist to work with the familiar pandas-like API on large datasets managed by Spark.
Reference
Pandas API on Spark Documentation: https://spark.apache.org/docs/latest/api/python/user_guide/pandas_on_spark/index.html
NEW QUESTION # 75
A data scientist has produced three new models for a single machine learning problem. In the past, the solution used just one model. All four models have nearly the same prediction latency, but a machine learning engineer suggests that the new solution will be less time efficient during inference.
In which situation will the machine learning engineer be correct?
Answer: A
Explanation:
If the new solution requires that each of the three models computes a prediction for every record, the time efficiency during inference will be reduced. This is because the inference process now involves running multiple models instead of a single model, thereby increasing the overall computation time for each record.
In scenarios where inference must be done by multiple models for each record, the latency accumulates, making the process less time efficient compared to using a single model.
Reference:
Model Ensemble Techniques
NEW QUESTION # 76
A machine learning engineer is trying to perform batch model inference. They want to get predictions using the linear regression model saved at the path model_uri for the DataFrame batch_df.
batch_df has the following schema:
customer_id STRING
The machine learning engineer runs the following code block to perform inference on batch_df using the linear regression model at model_uri: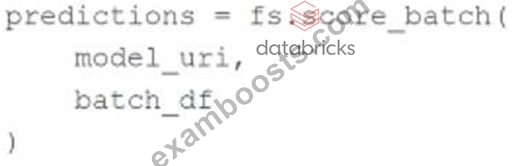
In which situation will the machine learning engineer's code block perform the desired inference?
Answer: E
Explanation:
The code block provided by the machine learning engineer will perform the desired inference when the Feature Store feature set was logged with the model at model_uri. This ensures that all necessary feature transformations and metadata are available for the model to make predictions. The Feature Store in Databricks allows for seamless integration of features and models, ensuring that the required features are correctly used during inference.
Reference:
Databricks documentation on Feature Store: Feature Store in Databricks
NEW QUESTION # 77
Which of the following tools can be used to distribute large-scale feature engineering without the use of a UDF or pandas Function API for machine learning pipelines?
Answer: B
Explanation:
Spark MLlib is a machine learning library within Apache Spark that provides scalable and distributed machine learning algorithms. It is designed to work with Spark DataFrames and leverages Spark's distributed computing capabilities to perform large-scale feature engineering and model training without the need for user-defined functions (UDFs) or the pandas Function API. Spark MLlib provides built-in transformations and algorithms that can be applied directly to large datasets.
Reference:
Databricks documentation on Spark MLlib: Spark MLlib
NEW QUESTION # 78
A data scientist is using Spark SQL to import their data into a machine learning pipeline. Once the data is imported, the data scientist performs machine learning tasks using Spark ML.
Which of the following compute tools is best suited for this use case?
Answer: B
Explanation:
For a data scientist using Spark SQL to import data and then performing machine learning tasks using Spark ML, the best-suited compute tool is a Standard cluster. A Standard cluster in Databricks provides the necessary resources and scalability to handle large datasets and perform distributed computing tasks efficiently, making it ideal for running Spark SQL and Spark ML operations.
Reference:
Databricks documentation on clusters: Clusters in Databricks
NEW QUESTION # 79
......
Our Databricks-Machine-Learning-Associate learning guide boosts many advantages and it is your best choice to prepare for the test. Firstly, our Databricks-Machine-Learning-Associate training prep is compiled by our first-rate expert team and linked closely with the real exam. So that if you practice with our Databricks-Machine-Learning-Associate Exam Questions, then you will pass for sure. Secondly, our Databricks-Machine-Learning-Associate study materials provide 3 versions and multiple functions to make the learners have no learning obstacles. They are the PDF, Software and APP online.
Databricks-Machine-Learning-Associate Free Updates: https://www.examboosts.com/Databricks/Databricks-Machine-Learning-Associate-practice-exam-dumps.html
DOWNLOAD the newest ExamBoosts Databricks-Machine-Learning-Associate PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1eKlmJ9bqt2fWfM5YBXYNEqtvvb0hr3d-
