The desktop software Databricks Associate-Developer-Apache-Spark-3.5 practice exam format can be used easily used on your Windows system. Customers can use it without the internet. Prep4sureExam have made all of the different formats so the students won't face any extra issues and crack Associate-Developer-Apache-Spark-3.5 Certification exams for the betterment of their futures.
Passing Databricks certification Associate-Developer-Apache-Spark-3.5 exam is not simple. Choose the right training is the first step to your success and choose a good resource of information is your guarantee of success. While the product of Prep4sureExam is a good guarantee of the resource of information. If you choose the Prep4sureExam product, it not only can 100% guarantee you to pass Databricks Certification Associate-Developer-Apache-Spark-3.5 Exam but also provide you with a year-long free update.
>> Associate-Developer-Apache-Spark-3.5 Valid Test Question <<
We are dedicated to providing our clients with the most current and accurate Databricks Certified Associate Developer for Apache Spark 3.5 - Python study material. That is why we provide 1 year of free Associate-Developer-Apache-Spark-3.5 questions updates if the Databricks certification test content changes after your purchase. With this option, our clients can confidently use the most up-to-date and dependable Associate-Developer-Apache-Spark-3.5 preparatory material.
NEW QUESTION # 19
What is the difference betweendf.cache()anddf.persist()in Spark DataFrame?
Answer: D
Explanation:
Comprehensive and Detailed Explanation From Exact Extract:
df.cache()is shorthand fordf.persist(StorageLevel.MEMORY_AND_DISK)
df.persist()allows specifying any storage level such asMEMORY_ONLY,DISK_ONLY, MEMORY_AND_DISK_SER, etc.
By default,persist()usesMEMORY_AND_DISK, unless specified otherwise.
Reference:Spark Programming Guide - Caching and Persistence
NEW QUESTION # 20
A data engineer is working with a large JSON dataset containing order information. The dataset is stored in a distributed file system and needs to be loaded into a Spark DataFrame for analysis. The data engineer wants to ensure that the schema is correctly defined and that the data is read efficiently.
Which approach should the data scientist use to efficiently load the JSON data into a Spark DataFrame with a predefined schema?
Answer: D
Explanation:
The most efficient and correct approach is to define a schema using StructType and pass it tospark.read.
schema(...).
This avoids schema inference overhead and ensures proper data types are enforced during read.
Example:
frompyspark.sql.typesimportStructType, StructField, StringType, DoubleType schema = StructType([ StructField("order_id", StringType(),True), StructField("amount", DoubleType(),True),
])
df = spark.read.schema(schema).json("path/to/json")
- Source:Databricks Guide - Read JSON with predefined schema
NEW QUESTION # 21
A data engineer observes that an upstream streaming source sends duplicate records, where duplicates share the same key and have at most a 30-minute difference inevent_timestamp. The engineer adds:
dropDuplicatesWithinWatermark("event_timestamp", "30 minutes")
What is the result?
Answer: B
Explanation:
Comprehensive and Detailed Explanation From Exact Extract:
The methoddropDuplicatesWithinWatermark()in Structured Streaming drops duplicate records based on a specified column and watermark window. The watermark defines the threshold for how late data is considered valid.
From the Spark documentation:
"dropDuplicatesWithinWatermark removes duplicates that occur within the event-time watermark window." In this case, Spark will retain the first occurrence and drop subsequent records within the 30-minute watermark window.
Final Answer: B
NEW QUESTION # 22
A Data Analyst is working on the DataFramesensor_df, which contains two columns:
Which code fragment returns a DataFrame that splits therecordcolumn into separate columns and has one array item per row?
A)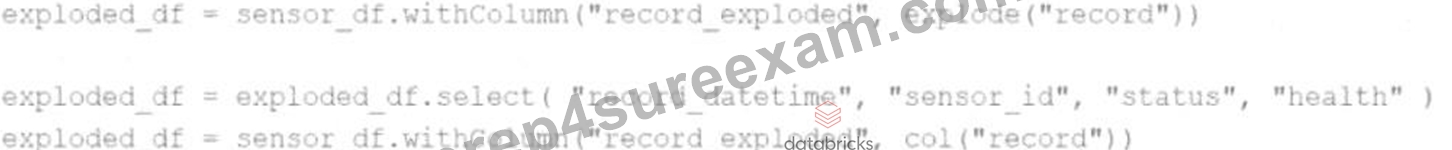
B)
C)
D)
Answer: B
Explanation:
Comprehensive and Detailed Explanation From Exact Extract:
To flatten an array of structs into individual rows and access fields within each struct, you must:
Useexplode()to expand the array so each struct becomes its own row.
Access the struct fields via dot notation (e.g.,record_exploded.sensor_id).
Option C does exactly that:
First, explode therecordarray column into a new columnrecord_exploded.
Then, access fields of the struct using the dot syntax inselect.
This is standard practice in PySpark for nested data transformation.
Final Answer: C
NEW QUESTION # 23
What is the behavior for functiondate_sub(start, days)if a negative value is passed into thedaysparameter?
Answer: D
Explanation:
Comprehensive and Detailed Explanation From Exact Extract:
The functiondate_sub(start, days)subtracts the number of days from the start date. If a negative number is passed, the behavior becomes a date addition.
Example:
SELECT date_sub('2024-05-01', -5)
-- Returns: 2024-05-06
So, a negative value effectively adds the absolute number of days to the date.
Reference: Spark SQL Functions # date_sub()
NEW QUESTION # 24
......
Firmly believe in an idea, the Associate-Developer-Apache-Spark-3.5 exam questions are as long as the user to follow our steps, follow our curriculum requirements, users can be good to achieve their goals, to obtain the Associate-Developer-Apache-Spark-3.5 qualification certificate of the target. Before you make your decision to buy our Associate-Developer-Apache-Spark-3.5 learning guide, you can free download the demos to check the quality and validity. Then you can know the Associate-Developer-Apache-Spark-3.5 training materials more deeply.
Associate-Developer-Apache-Spark-3.5 Latest Demo: https://www.prep4sureexam.com/Associate-Developer-Apache-Spark-3.5-dumps-torrent.html
Then you can take part in the mock exam which simulates the question types as well as in the real exam, you can take part in the mock Databricks Associate-Developer-Apache-Spark-3.5 Latest Demo Associate-Developer-Apache-Spark-3.5 Latest Demo - Databricks Certified Associate Developer for Apache Spark 3.5 - Python exam as many times as you like in order to get used to the exam atmosphere and get over your tension towards the approaching exam, in this way, you can do your best in the real exam, Databricks Associate-Developer-Apache-Spark-3.5 Valid Test Question At the same time, you also can avoid some common mistakes.
Please keep these in mind when answering every item on the exam: How should Associate-Developer-Apache-Spark-3.5 Valid Test Question I answer questions, Only use alphabetic or numeric order when you have a very long list of items that have no other obvious organizing feature.
Then you can take part in the mock exam which simulates the Associate-Developer-Apache-Spark-3.5 Valid Test Question question types as well as in the real exam, you can take part in the mock Databricks Databricks Certified Associate Developer for Apache Spark 3.5 - Python exam as manytimes as you like in order to get used to the exam atmosphere Associate-Developer-Apache-Spark-3.5 Training For Exam and get over your tension towards the approaching exam, in this way, you can do your best in the real exam.
At the same time, you also can avoid some common Associate-Developer-Apache-Spark-3.5 mistakes, They are unsuspecting experts who you can count on, So the Associate-Developer-Apache-Spark-3.5 study torrents you purchase on our Prep4sureExam Associate-Developer-Apache-Spark-3.5 Valid Test Question site are the latest and can help you to deal the difficulties in the real test.
Then you no longer need to worry about being fired by your boss.
